


htop, but for RDMA traffic — a real-time TUI monitor for RDMA network interfaces.
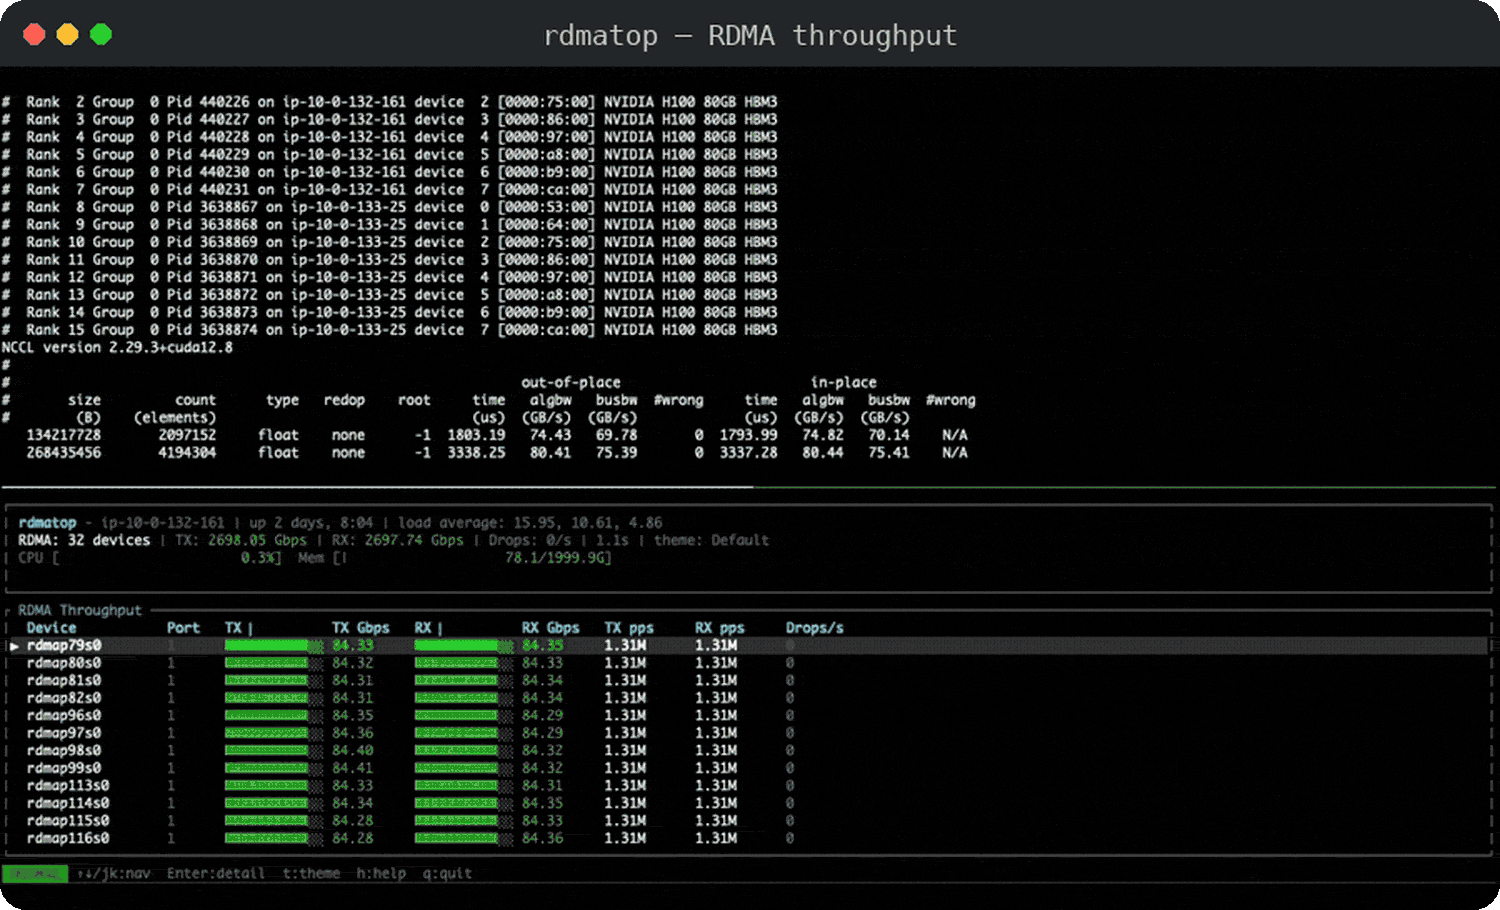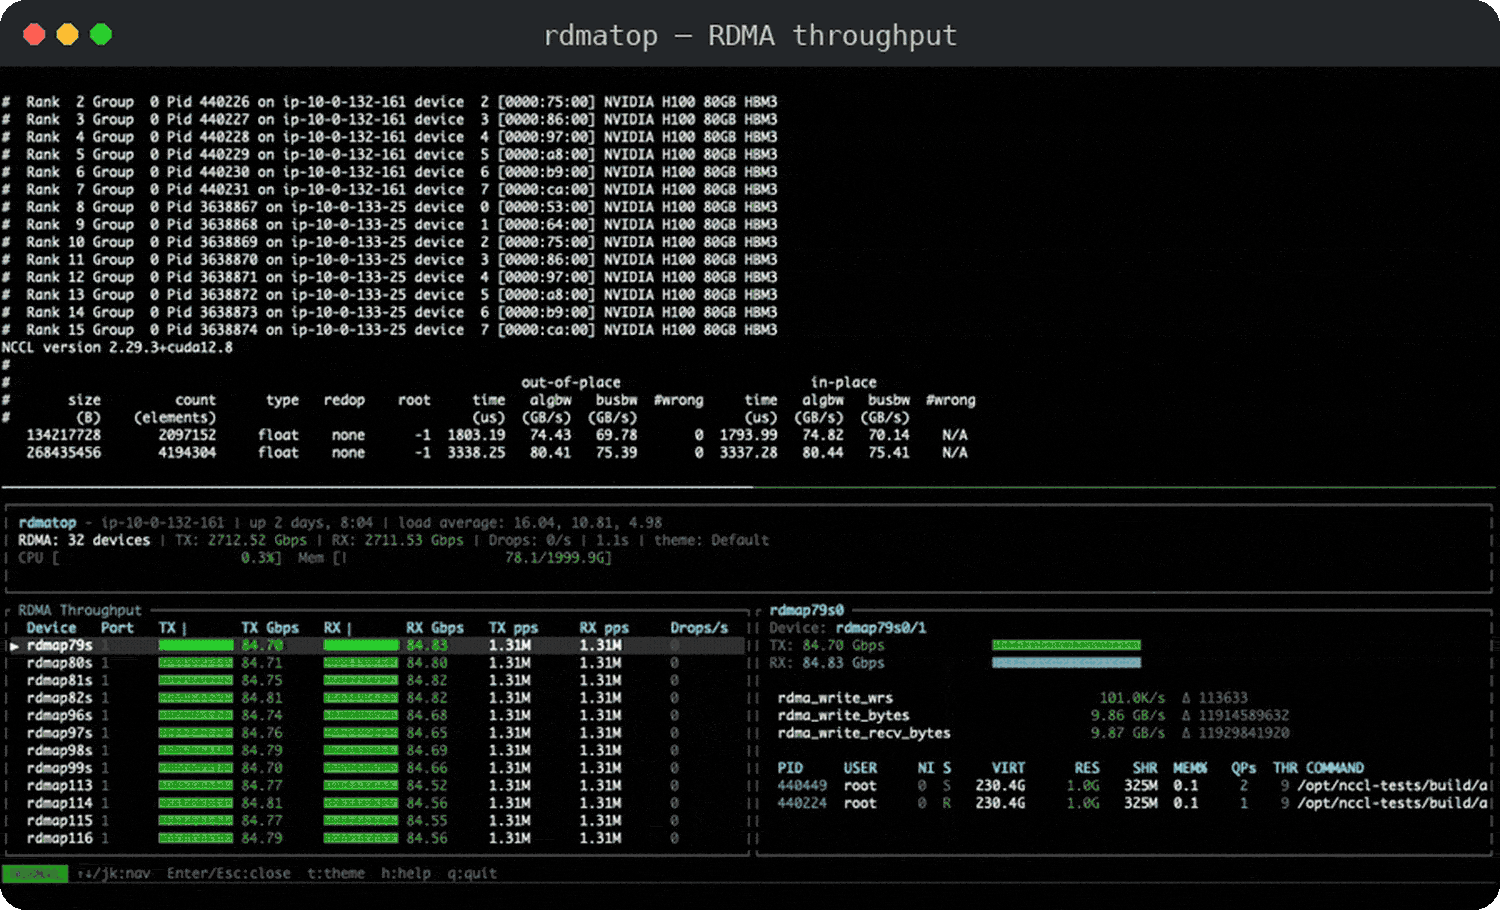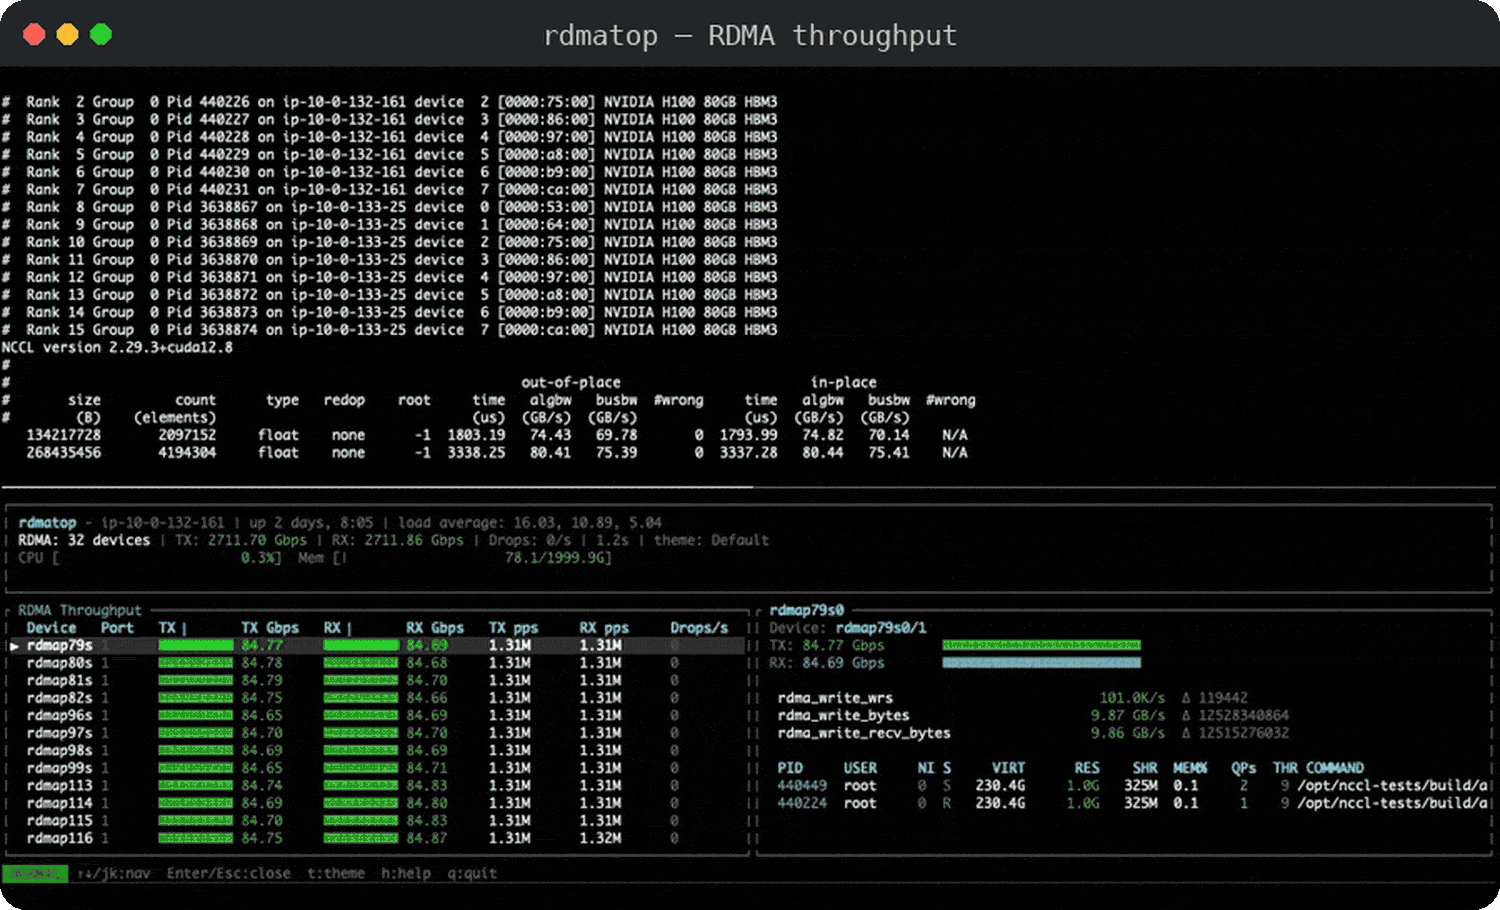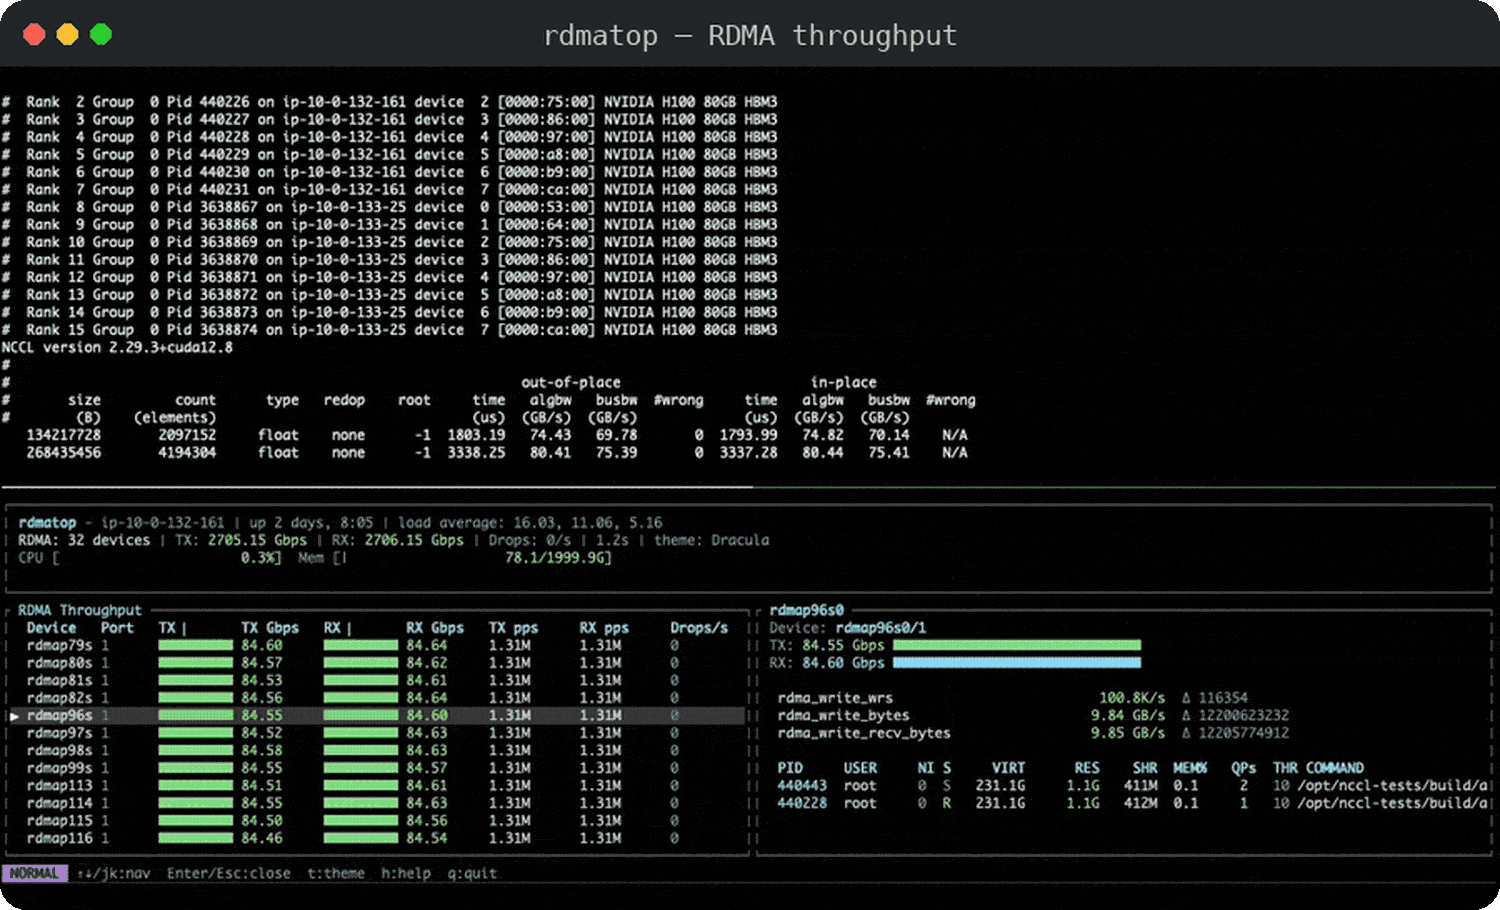
Monitors per-device throughput (Gbps, packets/s, drops), RDMA read/write counters, retransmits, health events, and shows which processes are using each RDMA device — all via RDMA netlink, the same interface used by rdma statistic.
- rdmatop: Cross-Provider htop for RDMA Traffic (2026-06-15)
- NVSHMEM Multi-NIC Support with AWS EFA (2026-03-27)
- Linux (netlink-based — macOS/Windows are not supported)
- RDMA-capable NICs (e.g., Mellanox/NVIDIA ConnectX, AWS EFA)
pip install rdmatopOn Ubuntu 22.04 (jammy), 24.04 (noble), or 26.04 (resolute) — amd64 and arm64:
sudo add-apt-repository ppa:crazyguitar/rdmatop
sudo apt update
sudo apt install rdmatopcargo install rdmatopmake # cargo build
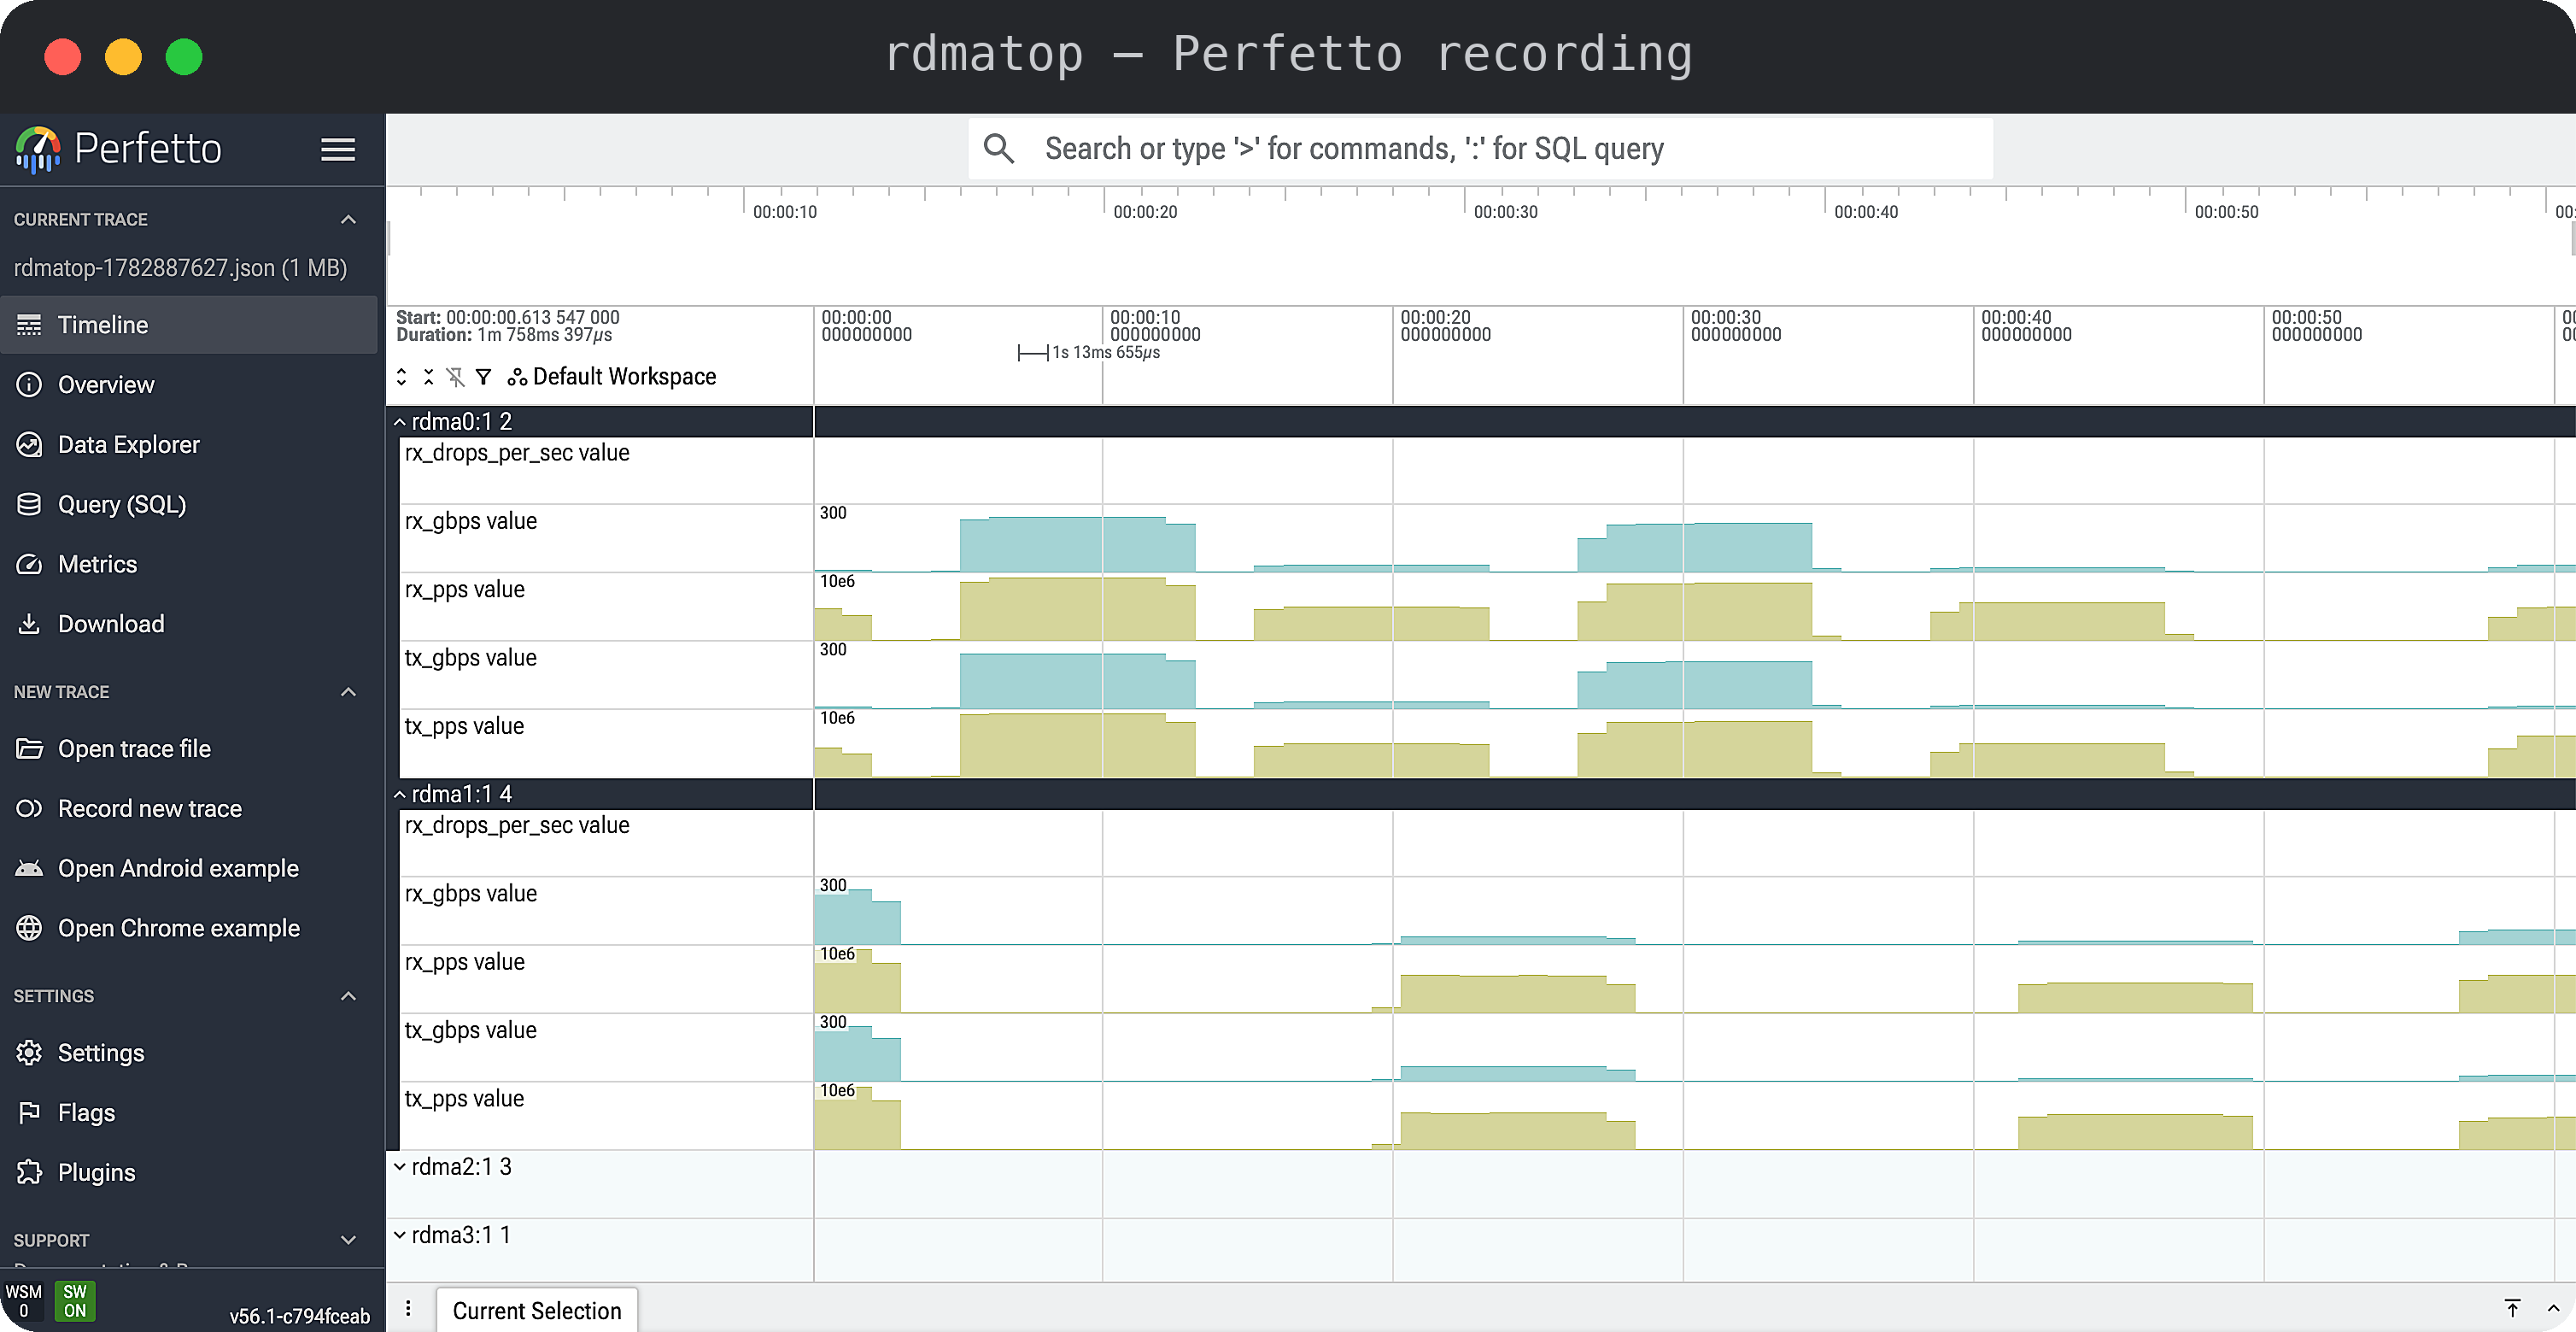
make install # cargo installrdmatopPress r to start and stop recording. rdmatop writes rdmatop-<timestamp>.json
to the current directory; open it in ui.perfetto.dev.
Build from a checkout (needs cargo and a C++ compiler; rebuild after
upgrading torch):
pip install "setuptools>=77" "torch>=2.9"
pip install --no-build-isolation -e .
Call enable() before profiling; RDMA counters land in the same trace:
import rdmatop.kineto
from torch.profiler import ProfilerActivity, profile

rdmatop.kineto.enable()
with profile(activities=[ProfilerActivity.CPU, ProfilerActivity.CUDA]) as prof:
    train_step()
prof.export_chrome_trace("trace.json")Add RDMA counters to a VizTracer trace from the CLI:
pip install "viztracer>=1.1.1"
viztracer --plugins rdmatop.viztracer -- my_script.py
Or in code:
from viztracer import VizTracer

with VizTracer(plugins=["rdmatop.viztracer"], output_file="trace.json"):
    train_step()
Set the sampling interval (ms, default 10) and limit to specific devices:
viztracer --plugins "rdmatop.viztracer --interval 1 --devices mlx5_0,mlx5_1" -- my_script.pyUse rdmatop to monitor RDMA traffic while running GPU
communication benchmarks:
- PyTorch — intranode NVLink/XGMI traffic
- IB Perftest — two-node
ib_write_bwbenchmark - UCX Perftest — two-node
ucx_perftestbandwidth / latency - NCCL — collective communication
- NIXL — point-to-point KV cache transfer
- NVSHMEM — one-sided GPU communication
- PPLX Kernels — MoE all-to-all dispatch/combine
- UCCL — DeepEP-compatible expert-parallel dispatch/combine
- RDMA Statistics — shell-based RDMA stats
- Kubernetes — DaemonSet deployment for Kubernetes
- Device enumeration —
RDMA_NLDEV_CMD_GETvia netlink to discover all RDMA devices - HW counters —
RDMA_NLDEV_CMD_STAT_GETper device/port, same asrdma statistic show - Process detection —
RDMA_NLDEV_CMD_RES_QP_GETto map QPs → PIDs, enriched with/procdata - Throughput — Two snapshots per interval, delta / elapsed for rates
See CONTRIBUTING.md for build/test instructions, design ground rules, and how to submit changes.
Apache-2.0